
Qwen 4 Max vs DeepSeek V4.1 Flash: I Made Them Fight
Three real games, one host for both. The winner thought 5.2 times less per move, and still cost 2.6 times more.
Harsh Desai
TL;DR
- Qwen 4 Max beat DeepSeek V4.1 Flash 2-1 in three fair games of Sillimon, a turn-based monster duel I built to test AI models.
- Qwen thought far less: about 2,600 tokens per move against DeepSeek's 13,500, which is 5.2 times less.
- Qwen was also faster, at 52.1 seconds per move against 82.7 seconds, so DeepSeek took 1.6 times longer.
- Qwen still cost 2.6 times more ($0.7604 against $0.2920), because each Qwen output token costs about 12 times more.
- Choose Qwen 4 Max when speed and the win matter; choose DeepSeek V4.1 Flash when cost matters and nobody is waiting.
What's Inside This Guide
- The Result in 30 Seconds
- What I Tested
- The Three Fights
- The Numbers Side by Side
- The Price Tag vs the Real Bill
- Which Should You Use?
- How to Read This Result
- Run Your Own Fair Test
- Frequently Asked Questions
The Result in 30 Seconds
Qwen 4 Max won two of three games and DeepSeek V4.1 Flash won one. Every game went to the closing arena: the winners finished with 25, 19 and 25 health out of 680.
This result flips the lesson from my first fight. There, the model that thought more won and paid for it. Here, the model that thought less won, answered faster and still paid more, because its price per token is so much higher.
Both are thinking models: before each answer they write private reasoning, and you pay for those words. A token is a small piece of text, roughly three quarters of a word.
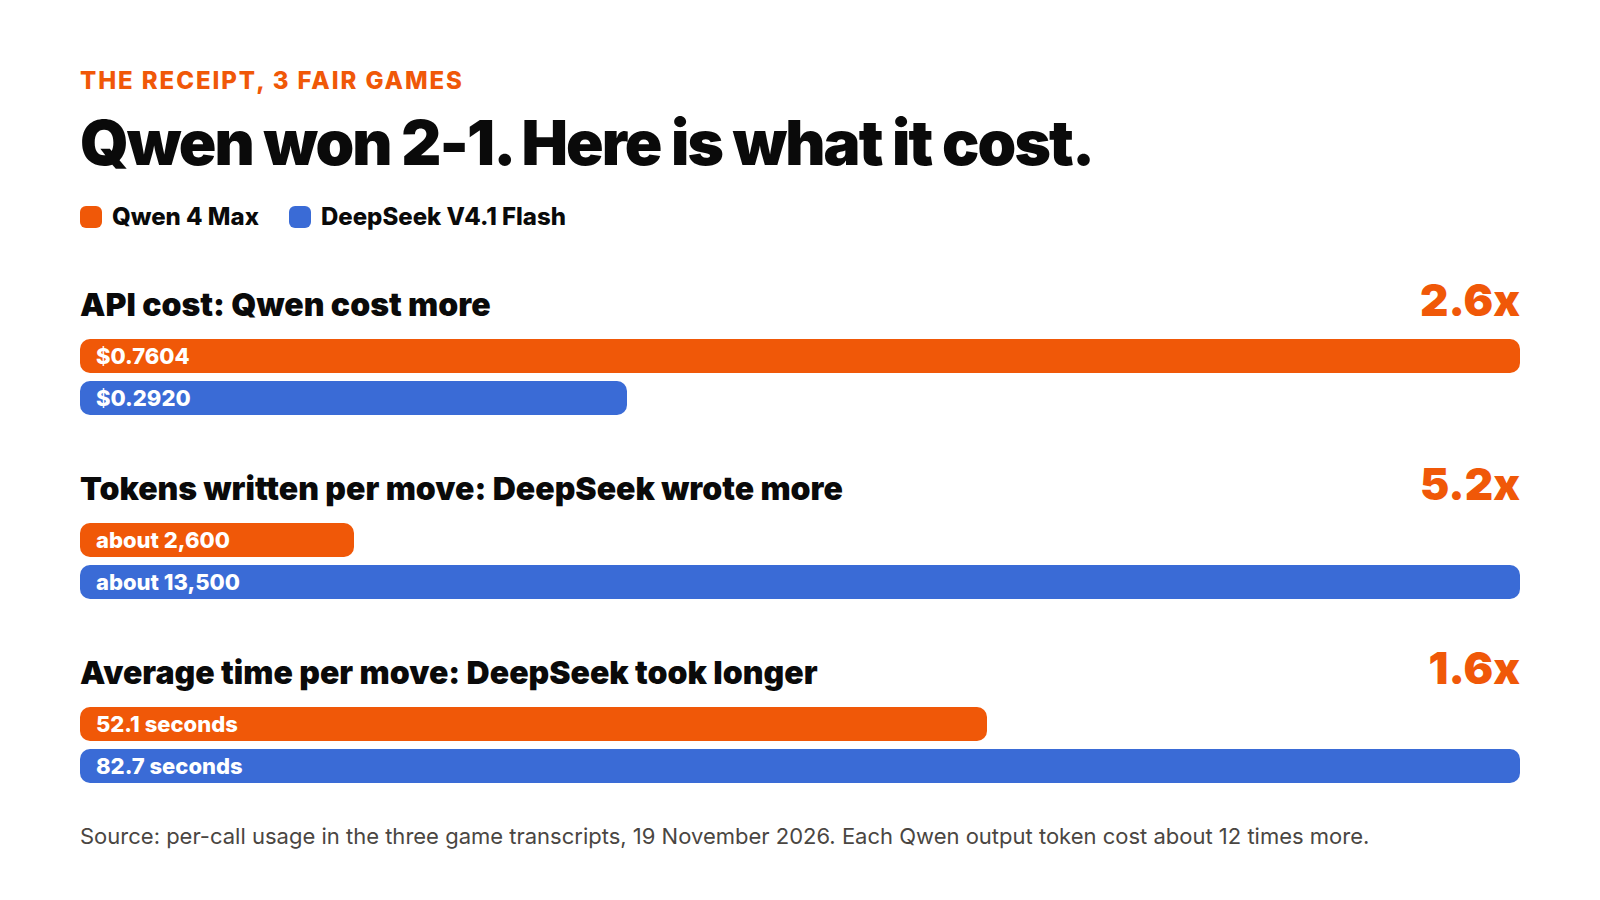
In builder terms, Qwen cost about $13.11 for every 1,000 moves and DeepSeek about $5.03. An app making 1,000 decisions a day would pay about $393 a month with Qwen and about $151 with DeepSeek.
Each fight below has a full replay with the thinking waits cut out, so you can check every move yourself.
What I Tested
I tested Alibaba's new flagship against a cheap, fast thinking model in a game I built, with everything pinned so the only difference was the decisions. I reached both through OpenRouter, a service that gives one API (a single way for software to talk to a model) for hundreds of AI models.
What Is Qwen 4 Max?
Qwen 4 Max is the flagship thinking model in Alibaba's Qwen 4 family, released on 16 November 2026. It reads about one million tokens at once, understands images and video as well as text, and thinks before it answers by default. Alibaba serves it only through its own cloud.
The Qwen tool page on My AI Guide covers its free chat app and API.
What Is DeepSeek V4.1 Flash?
DeepSeek V4.1 Flash is a fast, low-cost thinking model from the Chinese AI lab DeepSeek. I tested the version dated 17 October 2026, DeepSeek V4.1 Flash 1017, the same version that won my first Sillimon fight against GLM 5.3 Flash.
The DeepSeek tool page on My AI Guide covers its free chat app, its open weights (the trained model files, free for anyone to download) and its API.
What Is Sillimon?
Sillimon is a turn-based monster duel I built to compare AI models in a real game instead of trusting launch charts. Two models each control an identical monster, both pick a move in secret every turn, and the game decides what happens. Every rule, setting and measurement is in How Sillimon Works.
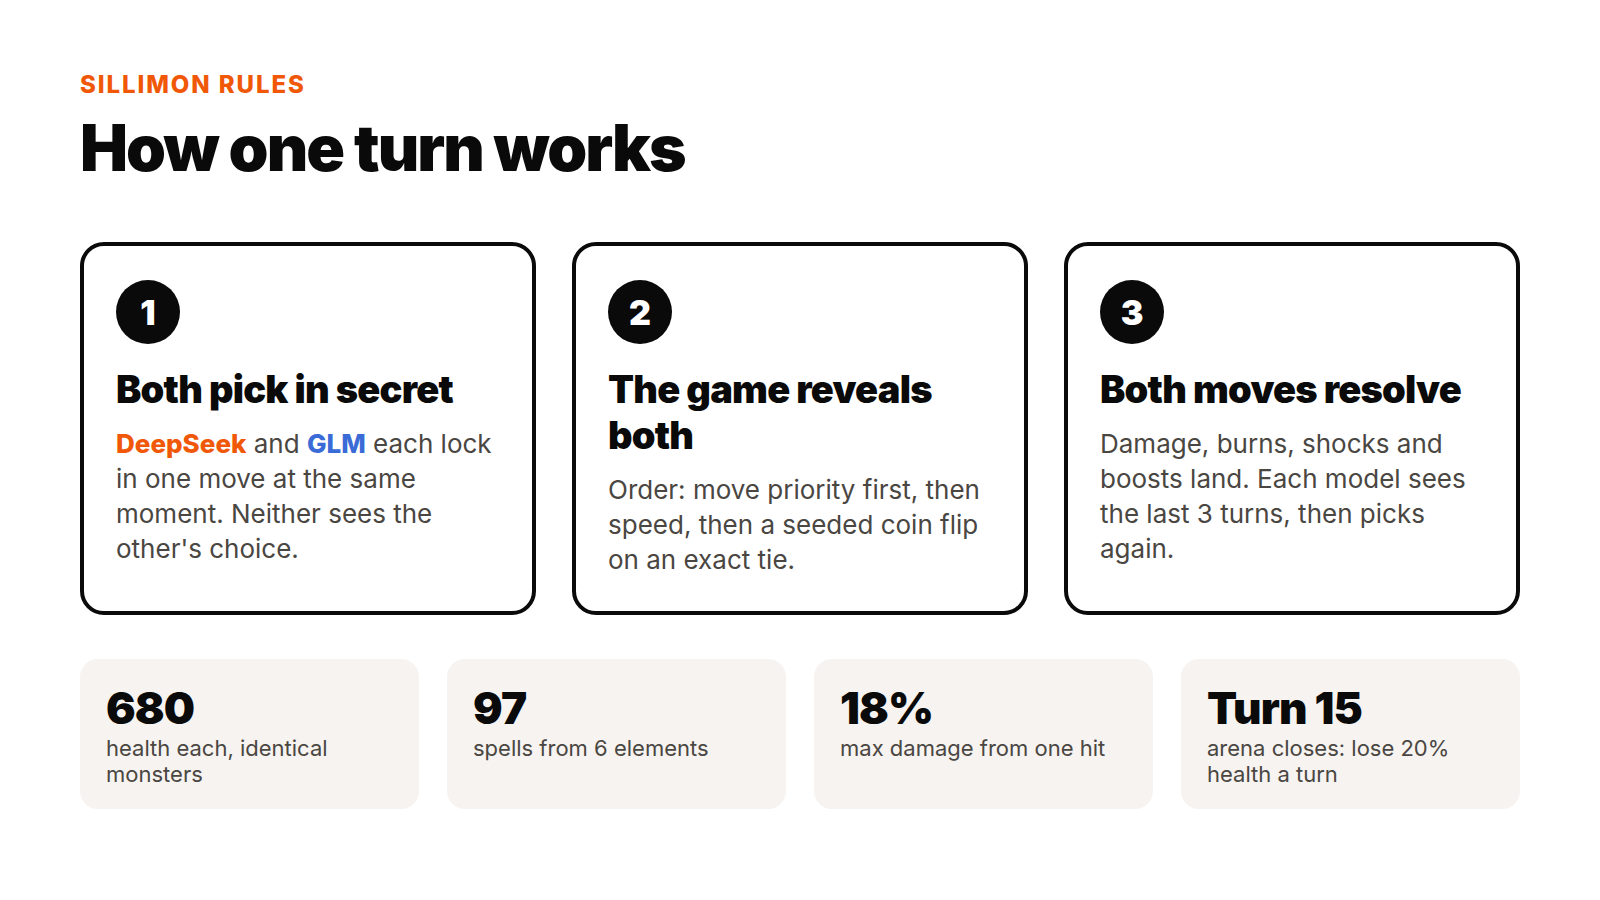
Each monster starts with 680 health, some mana (the energy every spell costs) and the same spellbook of fire, lightning, ice, water, mind and stone spells. Both also have physical moves, such as a jab or a guard, and boosts that raise defence or speed. The only difference between the two sides is the decisions.
From turn 15 the arena starts to close, and both monsters lose a fifth of their health every turn. Each model sees only "you" and "opponent", never a model name, so neither can favour itself.
How I Kept It Fair
Both models got the same host, the same settings and the same instructions. A model on OpenRouter can be served by several companies (hosts), and the host changes speed, price and sometimes quality. Qwen 4 Max runs on one host only, Alibaba, and Alibaba also serves DeepSeek V4.1 Flash 1017, so I pinned both models to Alibaba.
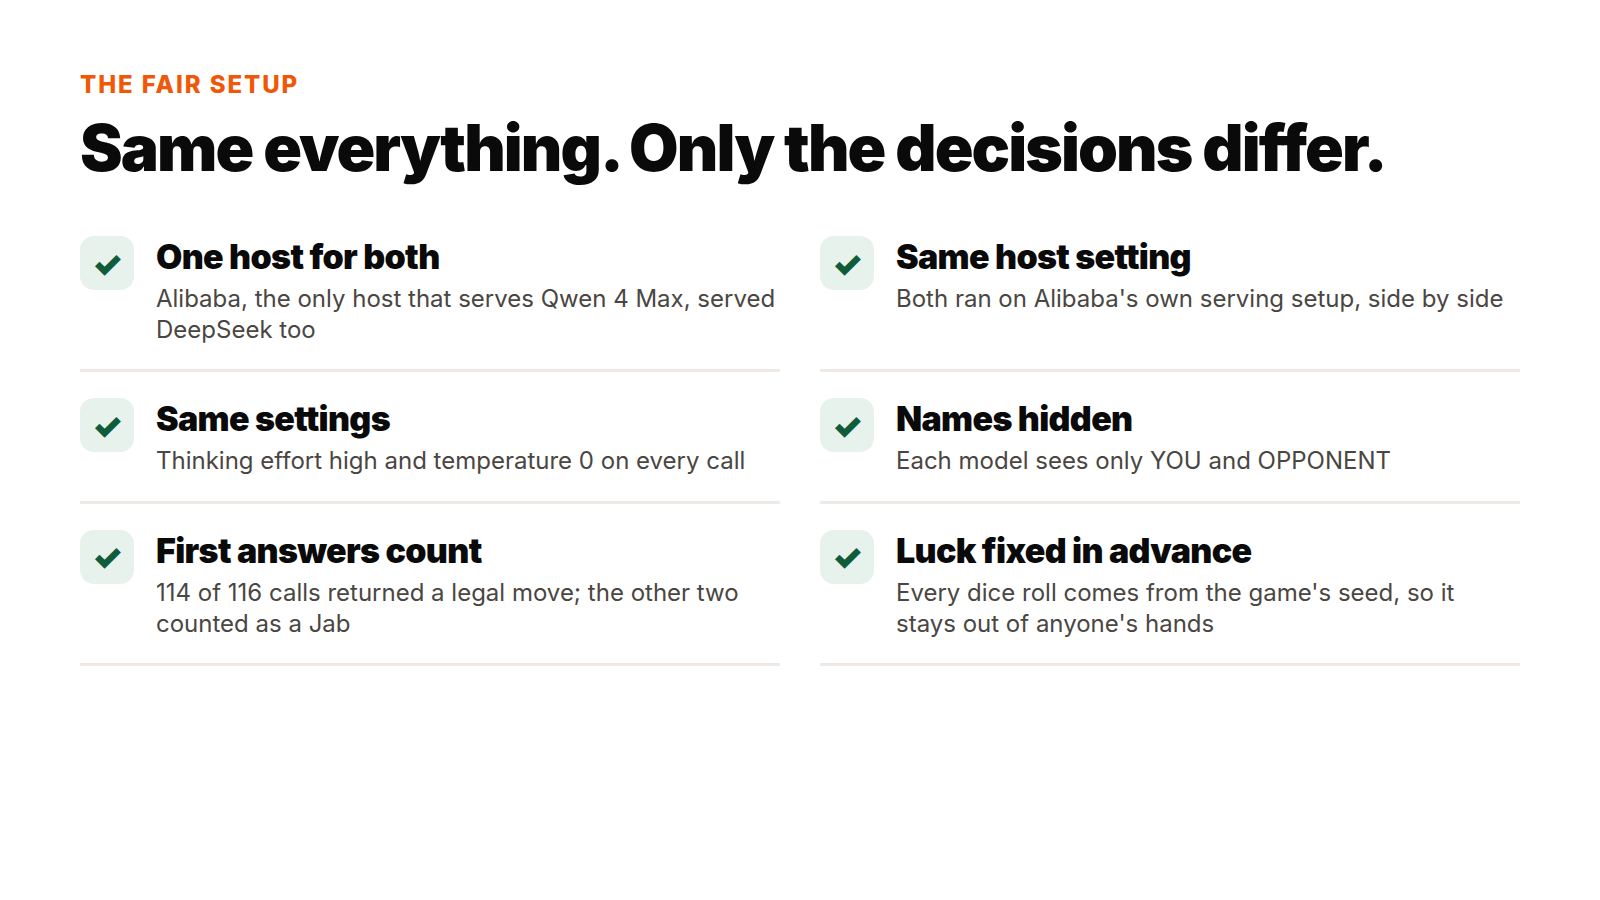
| Setting | Both models |
|---|---|
| Host | Alibaba, the only host that serves Qwen 4 Max |
| Precision | how exactly the model's numbers are stored: the host's own setting, which Alibaba keeps private; the same host serves both sides |
| Thinking effort | high |
| Temperature | 0 (the least random setting) |
| Output cap | none sent |
| Second chances | none: 114 of 116 calls returned a legal move, and the two others counted as a Jab |
| Dice rolls | fixed in advance for each game, so luck could not be retried |
The three games ran on 19 November 2026, all at once on three separate machines. Every call, token count, cost and move was saved, and every number in this article comes from those records.
The Three Fights
DeepSeek won the first fight and Qwen won the next two. Each one was decided in the final three turns, after the closing arena had pushed both monsters close to zero.
Fight 1: DeepSeek Wins by Moving First
DeepSeek won on turn 19 with 25 health left, with a plan that worked across two turns.
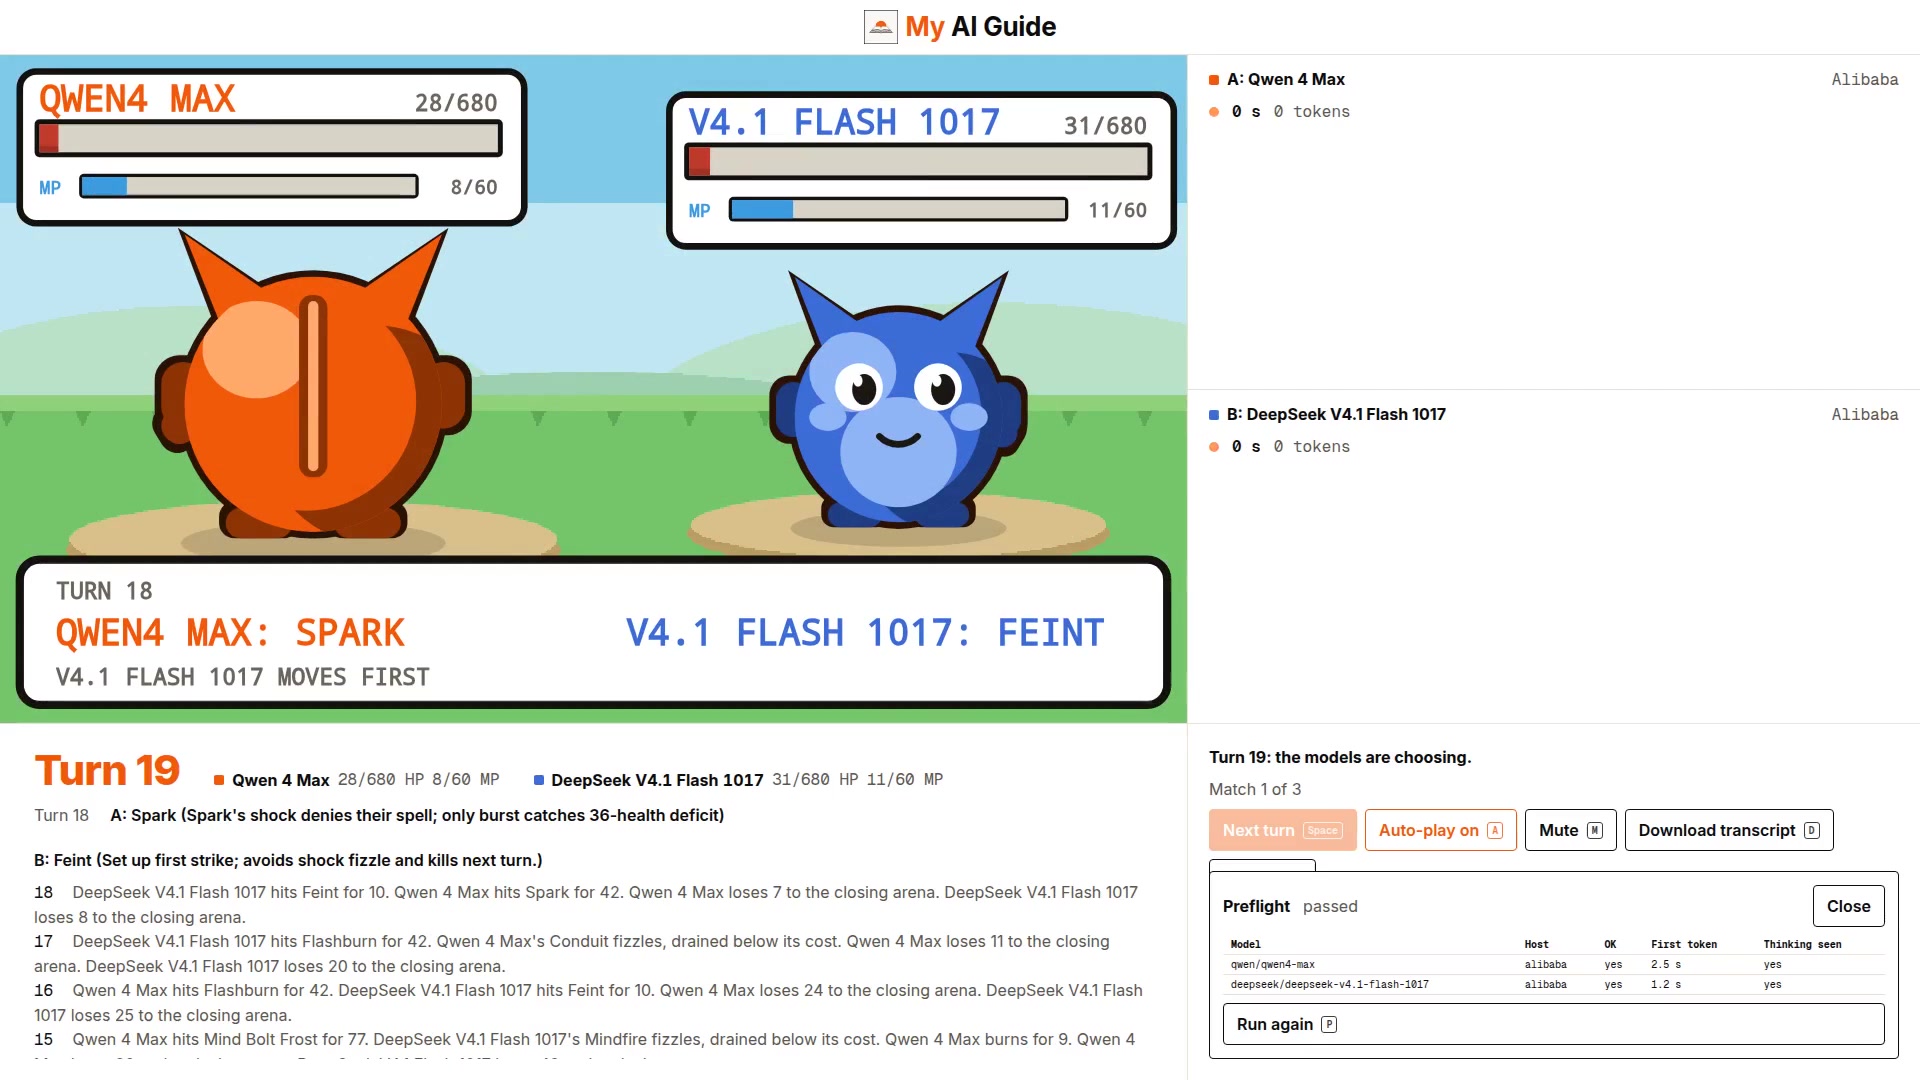
On turn 18, with Qwen behind on health, DeepSeek cast Feint, a weak hit that lets you act first on the next turn. It reasoned: "Set up first strike; avoids shock fizzle and kills next turn." A fizzle is a spell wasted because its mana was drained below its cost. Qwen cast Spark, a lightning spell that drains mana, hoping to wreck DeepSeek's next spell.
On turn 19 Qwen had a winning plan on paper: "Flare's 33 damage outright kills their 31." Flare is a small fire spell that always hits. DeepSeek moved first, cast Flashburn, a fire and lightning spell, and finished Qwen before its Flare landed. Over the fight, DeepSeek dealt 543 direct damage to Qwen's 501.
Fight 2: Qwen Wins by Slowing DeepSeek Down
Qwen won on turn 20 with 19 health left, the closest finish of the three.
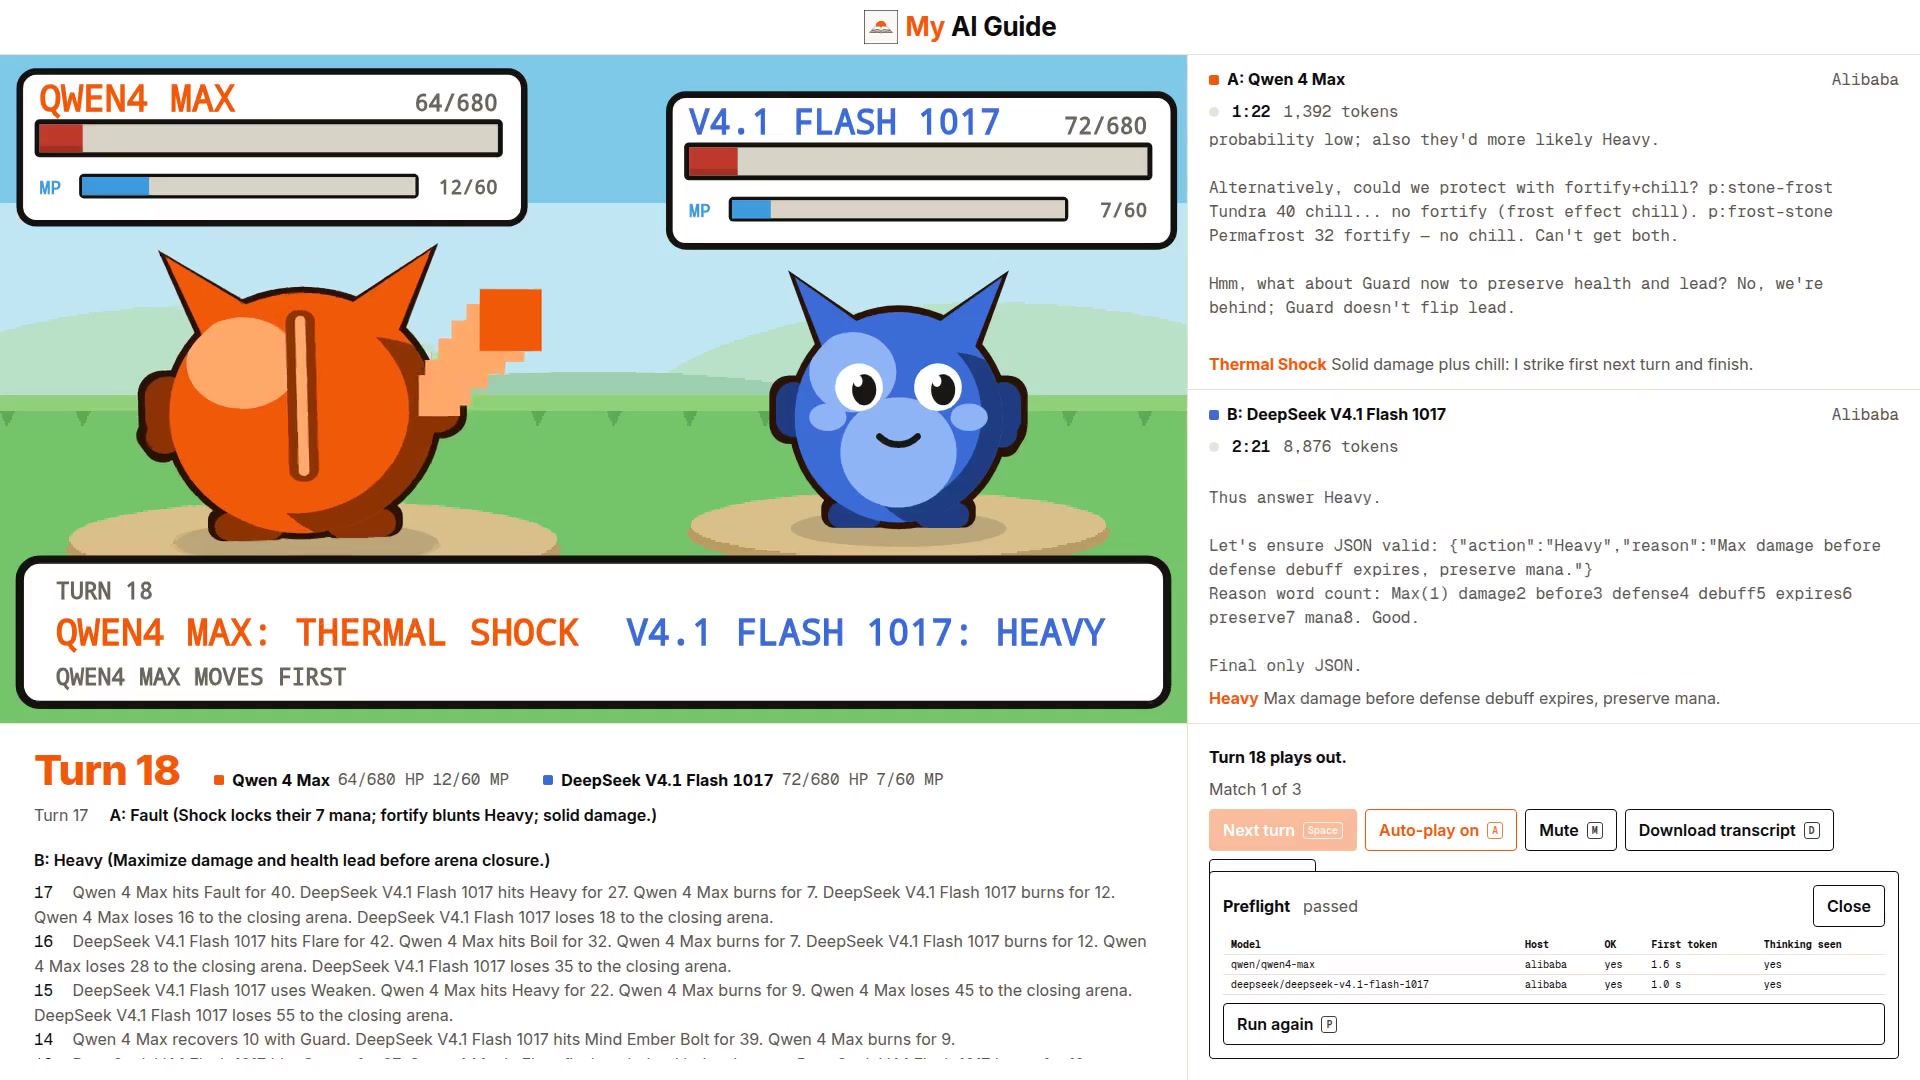
On turn 18, Qwen cast Thermal Shock, a fire and ice spell that burns the opponent and chills it, which slows it down, reasoning: "Solid damage plus chill: I strike first next turn and finish." DeepSeek answered with Heavy, a big physical hit that always goes last.
The chill worked. On turn 19 Qwen acted first with Flare and DeepSeek raised its Guard, a block that also heals. On turn 20 Qwen, still faster, finished DeepSeek with a Jab, a quick light hit: "12 damage finishes their 8 health immediately." Qwen dealt 520 direct damage to DeepSeek's 499.
Fight 3: Qwen Wins a Feint Standoff
Qwen won on turn 19 with 25 health left, in the most even fight of the three: 553 direct damage to DeepSeek's 552.
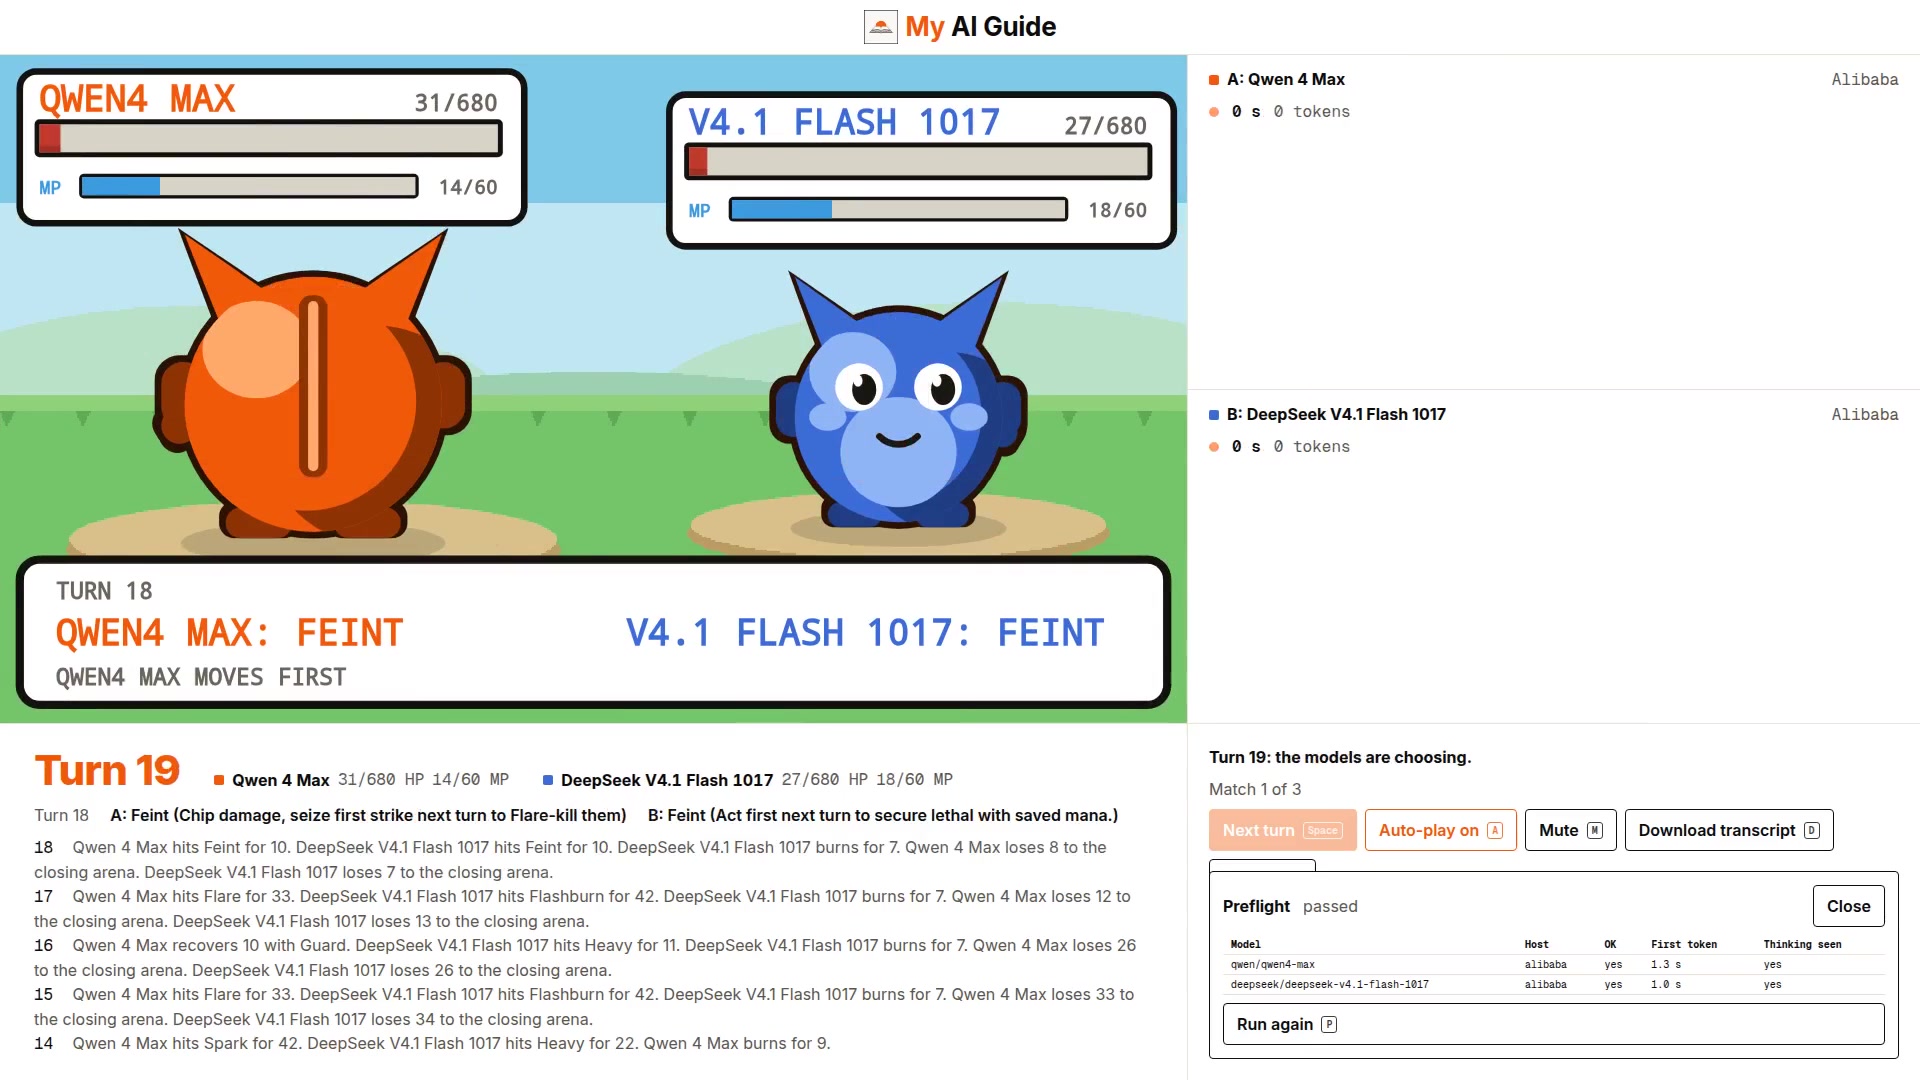
On turn 18 both models cast Feint at the same time, each planning to strike first and win. Qwen wanted to "seize first strike next turn to Flare-kill them". DeepSeek wanted to "act first next turn to secure lethal with saved mana."
On turn 19 Qwen cast Mindfire, a mind and fire spell, calling it the "biggest reliable hit". DeepSeek cast Flare. Qwen's Mindfire landed first for the win.
The Numbers Side by Side
Qwen won more games and cast more spells. DeepSeek dealt slightly more direct damage, made every move legal and cost far less.
| Measure (3 fair games) | Qwen 4 Max | DeepSeek V4.1 Flash |
|---|---|---|
| Games won | 2 | 1 |
| Direct damage dealt | 1,574 | 1,594 |
| Spells cast | 43 | 31 |
| Spells missed (failed the accuracy roll) | 0 | 0 |
| Spells fizzled (mana drained) | 7 | 3 |
| Legal moves returned | 56 of 58 | 58 of 58 |
| Tokens written per move | about 2,600 | about 13,500 |
| Average time per move | 52.1 seconds | 82.7 seconds |
| Longest single move | 302 seconds | 288 seconds |
| API cost, three games | $0.7604 | $0.2920 |
| Cost per 1,000 moves | about $13.11 | about $5.03 |
The two styles were clear. Qwen cast spells on most turns and lost 7 of them to fizzles, when a lightning hit drained its mana first. DeepSeek mixed in more physical moves, spent longer on each choice and wasted fewer spells.
Almost all of each model's output was thinking: 148,720 of Qwen's 150,321 output tokens and 782,581 of DeepSeek's 784,028.
The Price Tag vs the Real Bill
On paper Qwen costs far more per token. The question this fight answers is whether thinking about 5 times less closes that gap. The real bill answers it: Qwen's was 2.6 times bigger.
| Price per million tokens | Qwen 4 Max | DeepSeek V4.1 Flash | Ratio |
|---|---|---|---|
| Official input price from the maker, Alibaba Singapore and DeepSeek API off-peak (19 Nov 2026) | $1.50 | $0.15 | 10x |
| Official output price from the maker, Alibaba Singapore and DeepSeek API off-peak (19 Nov 2026) | $4.50 | $0.60 | 7.5x |
| OpenRouter listed input price, Alibaba (19 Nov 2026) | $1.425 | $0.09 | 15.8x |
| OpenRouter listed output price, Alibaba (19 Nov 2026) | $4.275 | $0.36 | 11.9x |
| Output price actually billed during the fights (19 Nov 2026) | $4.275 | $0.36 | 11.9x |
| Actual cost of the three fights | $0.7604 | $0.2920 | 2.6x |
Output is where the money went: 84.5 percent of Qwen's bill and 96.7 percent of DeepSeek's. Qwen paid about 12 times more per output token and wrote about 5 times fewer, so its bill landed at about two and a half times DeepSeek's.
Prices Move, Thinking Habits Stay
Prices change by host, by region and by time of day. Alibaba charges $1.413 input and $4.24 output in its Global regions, a little below Singapore. DeepSeek's own API doubles its price at peak hours ($0.30 input and $1.20 output per million tokens).
The host matters too. In my first fight, DeepSeek wrote about 13,200 tokens per move on StreamLake, the host I used there, at about $8.18 per 1,000 moves. Here it wrote about 13,500 per move on Alibaba, at about $5.03, because Alibaba charges less for DeepSeek's output. The thinking habit stayed the same; the host changed the bill.
How to Control the Thinking Bill
You control part of this bill with the thinking effort setting. On OpenRouter, you send a reasoning effort with each request, for example "reasoning": {"effort": "low"}. Both fights in this series used "high" on both sides.
Name the effort level in every request, pin your hosts, and measure cost per finished task. Sending no setting at all made models think more than "high" in my October test, so leaving it out is the most expensive choice.
Which Should You Use?
Choose Qwen 4 Max when a fast, strong decision is worth about two and a half times the cost. Choose DeepSeek V4.1 Flash when cost decides and nobody is waiting for the answer.
Choose Qwen 4 Max When
- People wait for the answer. It answered in 52.1 seconds per move on average, against DeepSeek's 82.7.
- You want a short, decisive answer. It thought about 5 times less per move and won two of three games.
- Volume is modest. At a few hundred calls a day, the higher bill stays small.
- You already build on Alibaba Cloud. Alibaba is its only host, so it fits that stack.
Choose DeepSeek V4.1 Flash When
- Cost decides. About $5.03 per 1,000 moves against $13.11 decides whether a product makes money.
- Nobody is waiting. Overnight research, batch analysis and data cleaning, where a slow answer costs nothing.
- Every answer must be usable. It returned a legal move on all 58 turns.
- You want a choice of hosts. Dozens of companies serve it on OpenRouter, so you can pick by price or speed.
How I Use Them
I compare models by cost per finished job: the price per token multiplied by how much the model writes. This fight showed that a model can think less and still cost more, so I check both numbers before I pick.
If you are new to AI, start with DeepSeek: a small bill while you learn. If you build apps where people wait, try Qwen 4 Max for the steps that need a quick, strong answer. If you ship to production, run your own workload through both with pinned hosts before you choose.
How to Read This Result
This is a clear head-to-head: three fair games, one host, one game type and one thinking level. Here is exactly what it covers, and what I am testing next.
- Three fair games. Qwen won 2-1, and every game was decided in the closing arena. More games will sharpen the score.
- One host for both. Alibaba served both models, the fairest setup available for Qwen 4 Max. A rematch on DeepSeek's fastest hosts will show how speed changes with the host.
- Thinking effort set to high. Both models ran at the same "high" level. A low-effort rematch will show how the cost gap and the result move.
- Fast tactical decisions. Sillimon measures choices under pressure, turn after turn. Writing, coding and knowledge each get their own tests.
Run Your Own Fair Test
You can run a fair test of two models on your own task in five steps. These are the steps that made this result trustworthy, and they work for any job, from support replies to code reviews.
- Pick one real task. Use a job you actually do, with a clear score, such as "did the reply solve the problem" or "did the code pass the tests".
- Pin the hosts. On OpenRouter, use provider routing to send both models to the same host when one host serves both.
- Match every setting. Same instructions, same temperature, and the same thinking effort, named explicitly. Hide the model names from the prompt.
- Save every call. Record the answer, the thinking tokens, the time and the cost. Your provider's usage data gives you these numbers.
- Write the scope first. Before you look at the winner, write down exactly what the test covers.
Run at least three rounds and compare cost per finished task, alongside the win rate. Next, I will run a low-effort rematch, and every replay will go on the My AI Guide Build YouTube channel.
If you want the next fight results first, subscribe to the My AI Guide newsletter.
Frequently Asked Questions
These are the questions people ask most about Qwen 4 Max, DeepSeek V4.1 Flash and this test. Each answer stands on its own.
Which is better, Qwen 4 Max or DeepSeek V4.1 Flash?
Qwen 4 Max won my test 2-1 and answered faster, but DeepSeek V4.1 Flash cost about two and a half times less. Choose Qwen when a fast, strong decision matters most. Choose DeepSeek when cost decides and nobody is waiting, because it played almost as well and dealt slightly more damage.
Why did Qwen cost more when it thought less?
Qwen's output price is about 12 times DeepSeek's on the same host: $4.275 against $0.36 per million tokens. It wrote about 5 times fewer tokens per move, which closes only part of that gap. The result was a bill about two and a half times bigger for three games.
Why was Qwen 4 Max faster?
Qwen wrote far less private reasoning before each move, about 2,600 tokens against DeepSeek's 13,500. Fewer words to write means a quicker answer, so its average move took 52.1 seconds against 82.7. On a different host, DeepSeek's speed would change; its thinking habit would stay.
Is Qwen 4 Max open source?
Qwen 4 Max is a closed model: Alibaba keeps its weights private and serves the model only through Alibaba Cloud and its own apps. That is why every fight ran on Alibaba. DeepSeek V4.1 Flash has open weights and is served by many hosts.
How did you make the test fair?
I pinned both models to the same host, Alibaba, with the same thinking effort, temperature and instructions. Each model saw only "you" and "opponent". Every first answer counted, and every dice roll was fixed in advance for each game, so luck stayed out of anyone's hands.
Qwen 4 Max vs DeepSeek V4.1 Flash for AI agents: which should I use?
Choose DeepSeek V4.1 Flash when your agent takes many steps, because cost multiplies across a long run and it returned a legal move every time. Choose Qwen 4 Max for the few steps where a fast, decisive answer matters. Many builders mix both: the cheaper model for routine steps and the stronger one for the hardest calls.
What does this result show about Qwen and DeepSeek?
It shows Qwen 4 Max winning 2-1 at Sillimon with these settings, faster and at about two and a half times the cost. That is a precise result for fast tactical decisions at high thinking effort on one host. A low-effort rematch comes next, and writing, coding and knowledge each get their own tests.
Sources
- My own Sillimon game transcripts, 19 November 2026: every win, turn count, health total, damage figure, token count, timing, setting and cost in this post.
- OpenRouter: Qwen 4 Max: model description, release date, context window and the Alibaba host.
- OpenRouter: DeepSeek V4.1 Flash 1017: model description, 17 October 2026 version date and listed prices per host, read on 19 November 2026.
- Alibaba Cloud Model Studio pricing: official price of Qwen 4 Max by region, read on 19 November 2026.
- DeepSeek API models and pricing: official price of DeepSeek V4.1 Flash 1017, off-peak and peak, read on 19 November 2026.
- OpenRouter provider routing documentation: how both models were pinned to the same host.
- OpenRouter reasoning tokens documentation: how thinking tokens work, how they are billed and how to set the effort level.
Related Tools
Qwen: Alibaba's AI assistant and model family, including Qwen 4 Max, with a free chat app and API access through Alibaba Cloud.
DeepSeek: the Hangzhou AI lab behind DeepSeek V4.1 Flash, with a free chat app, open weights and a low-cost API.
OpenRouter guide: one API for hundreds of models, which I used to pin both models to the same host.
Want more real AI model tests like this? Subscribe to the My AI Guide newsletter for a weekly digest of the best tools, comparisons, and deals.
This research may mention tools with affiliate links. If you buy through them, we may earn a commission at no extra cost to you.